North America
Silicon Valley · Atlanta · West Texas · Toronto · Ontario
Across North America, Europe, the Middle East and Asia Pacific.
H100. H200. B200. B300. GB300. Vera Rubin. Global resources, connected.
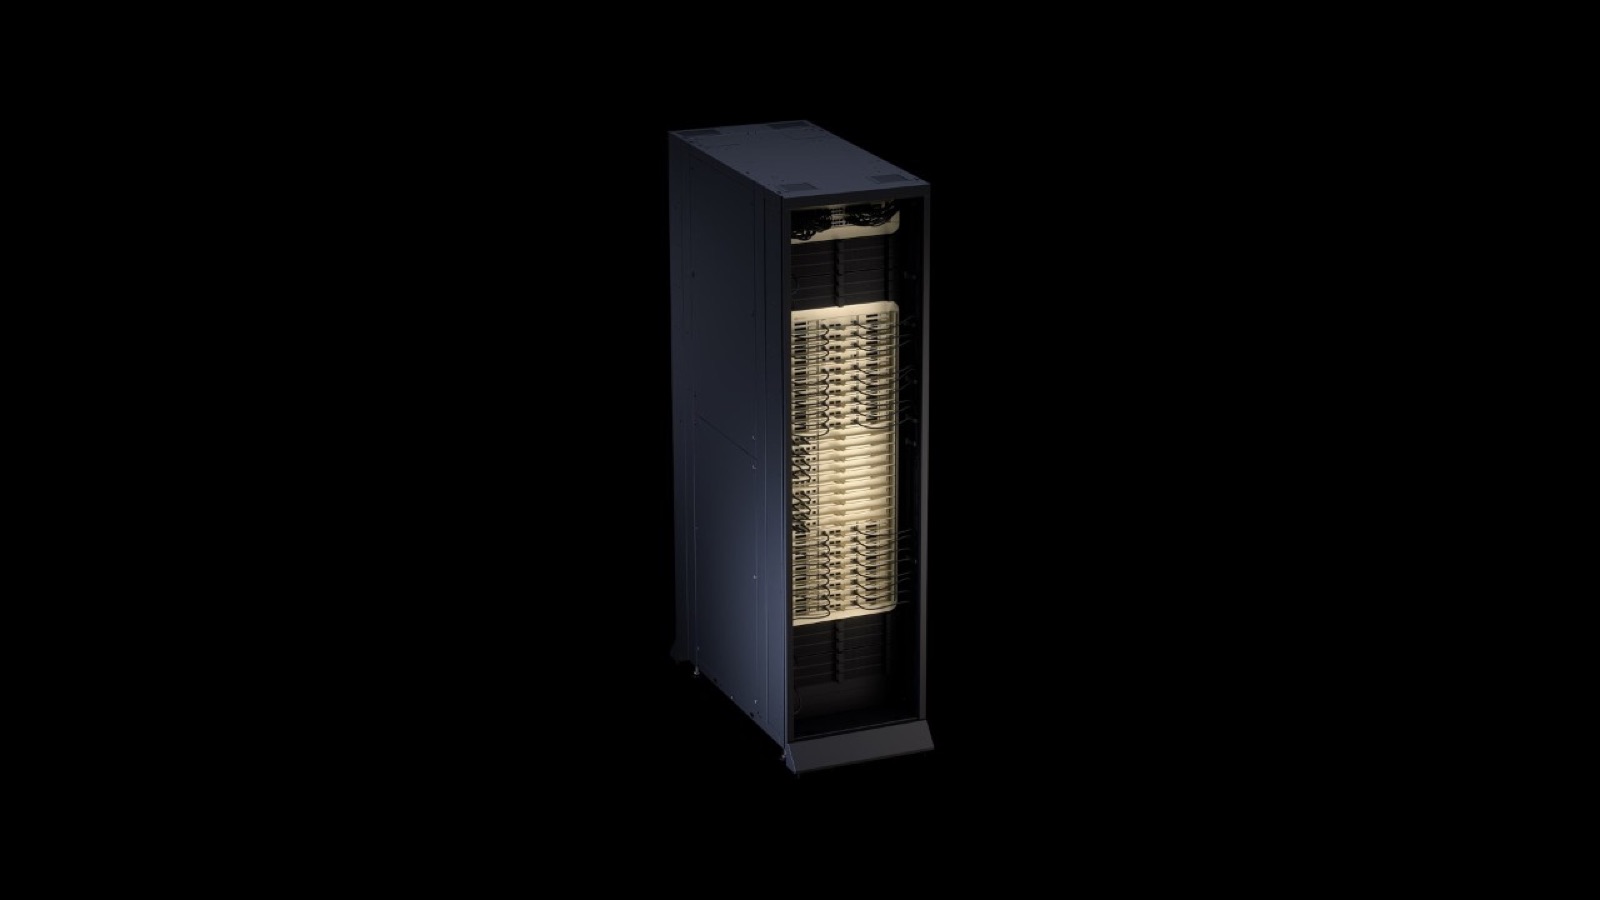 NVIDIA VERA RUBIN NVL72
From Silicon Valley to Seoul. From Blackwell Ultra to Vera Rubin. Connect your AI ambitions with GPU infrastructure across key global markets.
Silicon Valley · Atlanta · West Texas · Toronto · Ontario
United Kingdom · Romania
Abu Dhabi
Seoul · Yokohama · Jakarta · Singapore · Malaysia
Resource network includes capacity at different readiness stages. Locations and capacities describe sourcing options, not real-time stock or NEXFLOW-owned facilities. Toronto configurations are alternatives and are not added together.
Find the right location for your AI workload↗ JAPAN / KANTO · PROJECT BRIEF
Explore a Kanto-region B300 proposal combining dedicated GPU capacity with prefabricated liquid-cooled infrastructure.
Planning brief, September 2026. Image supplied as a modular pilot reference; not proof of completion of this project.
From H100 and H200 to Blackwell and Vera Rubin. Explore GPU server and cluster resource options around your workload and preferred region.
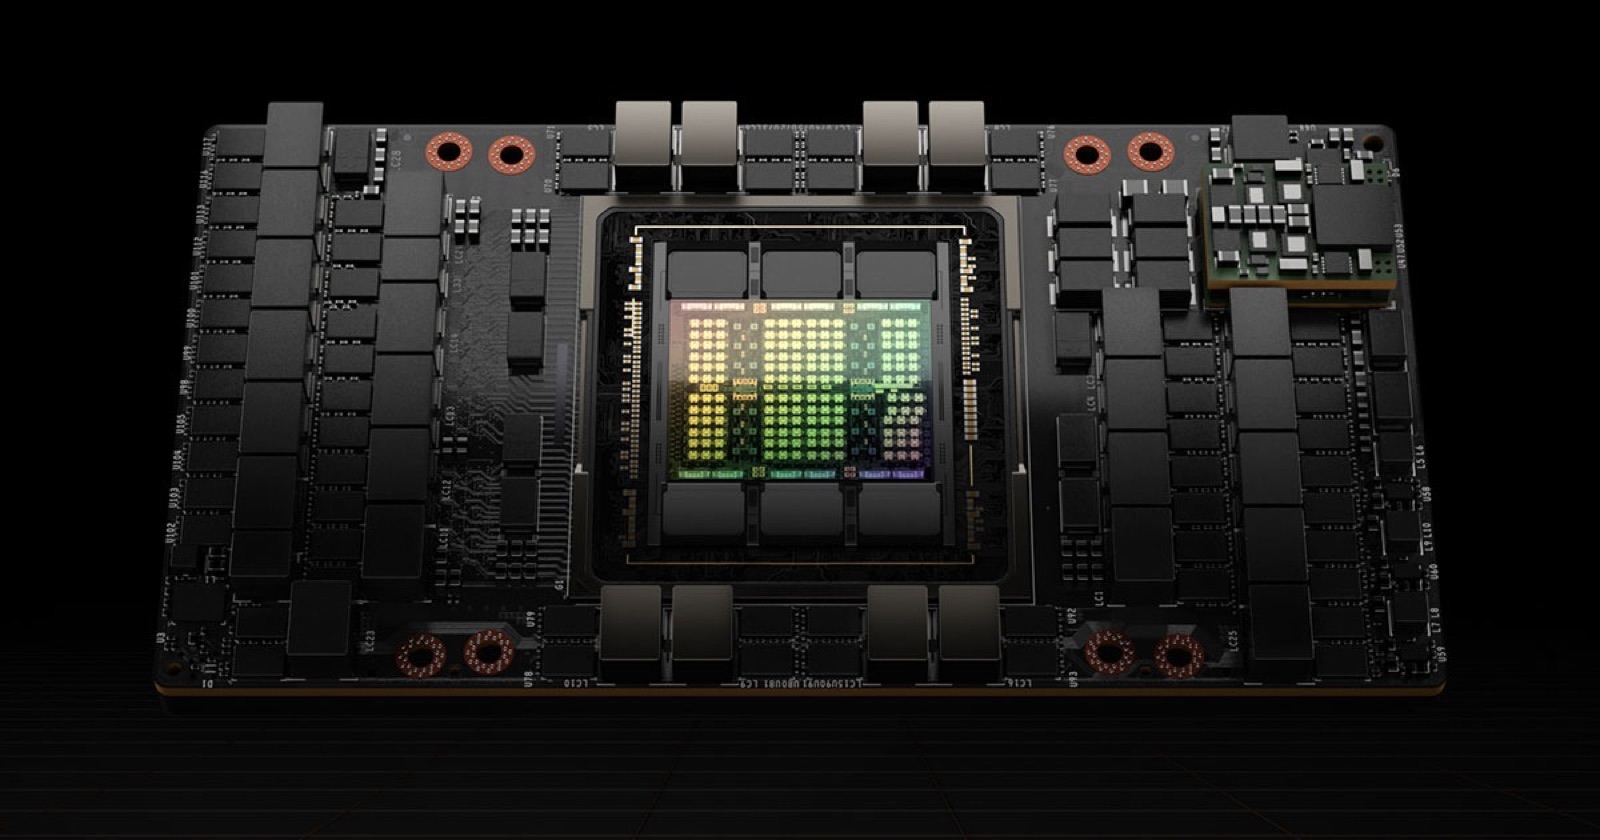
GPU resource enquiries for training and inference workloads.
Discuss H100 resources ↗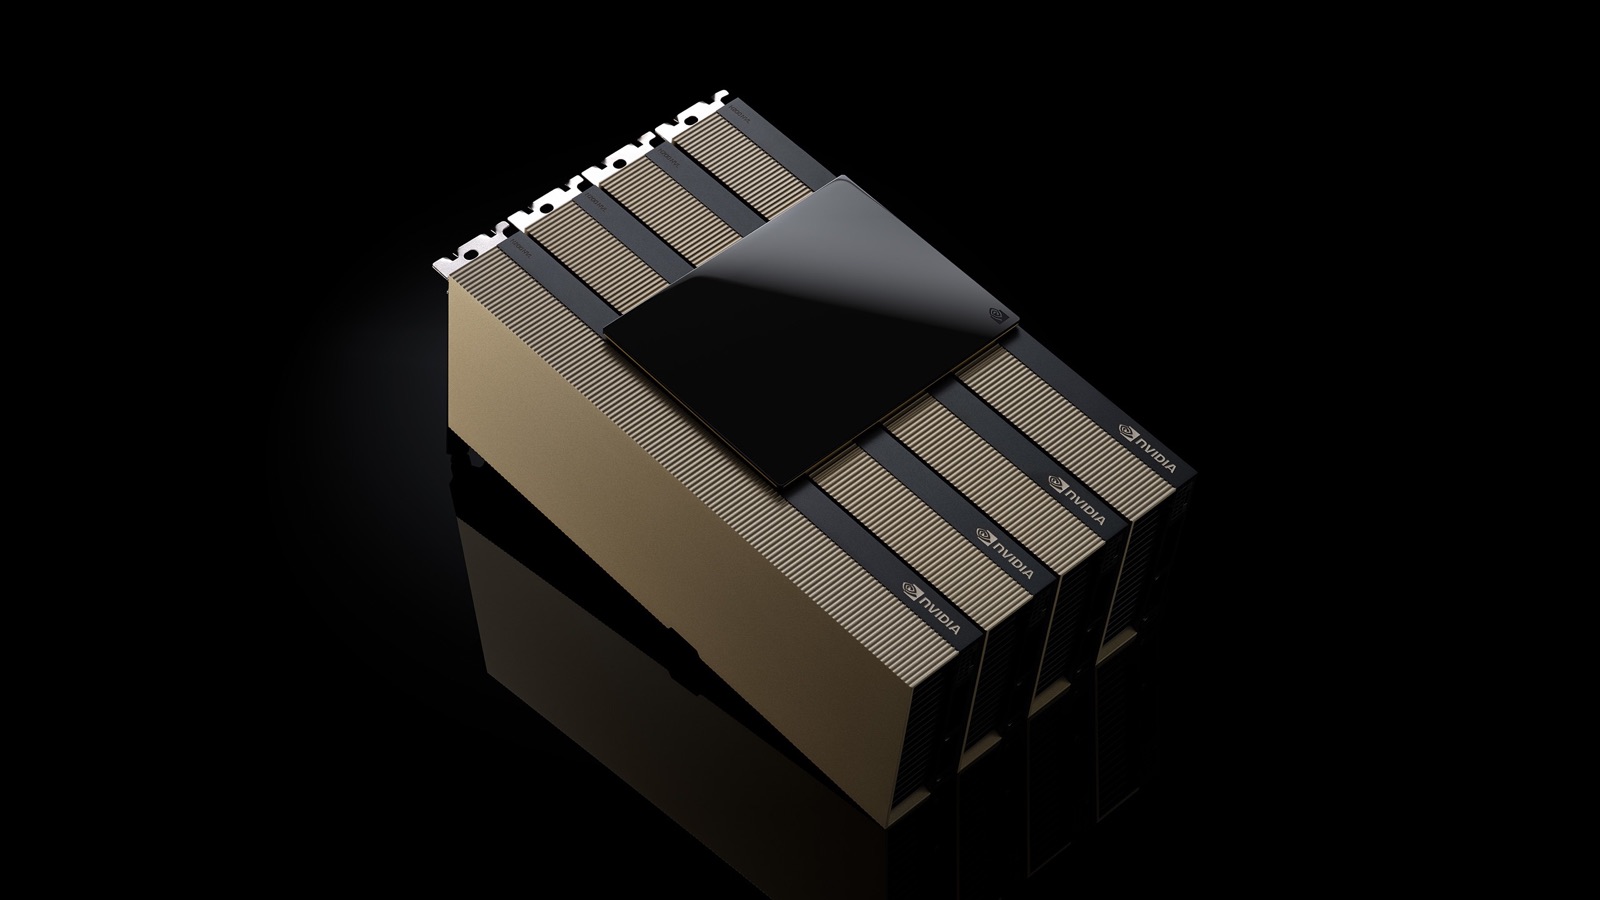
Explore resource options for memory-demanding AI workloads.
Discuss H200 resources ↗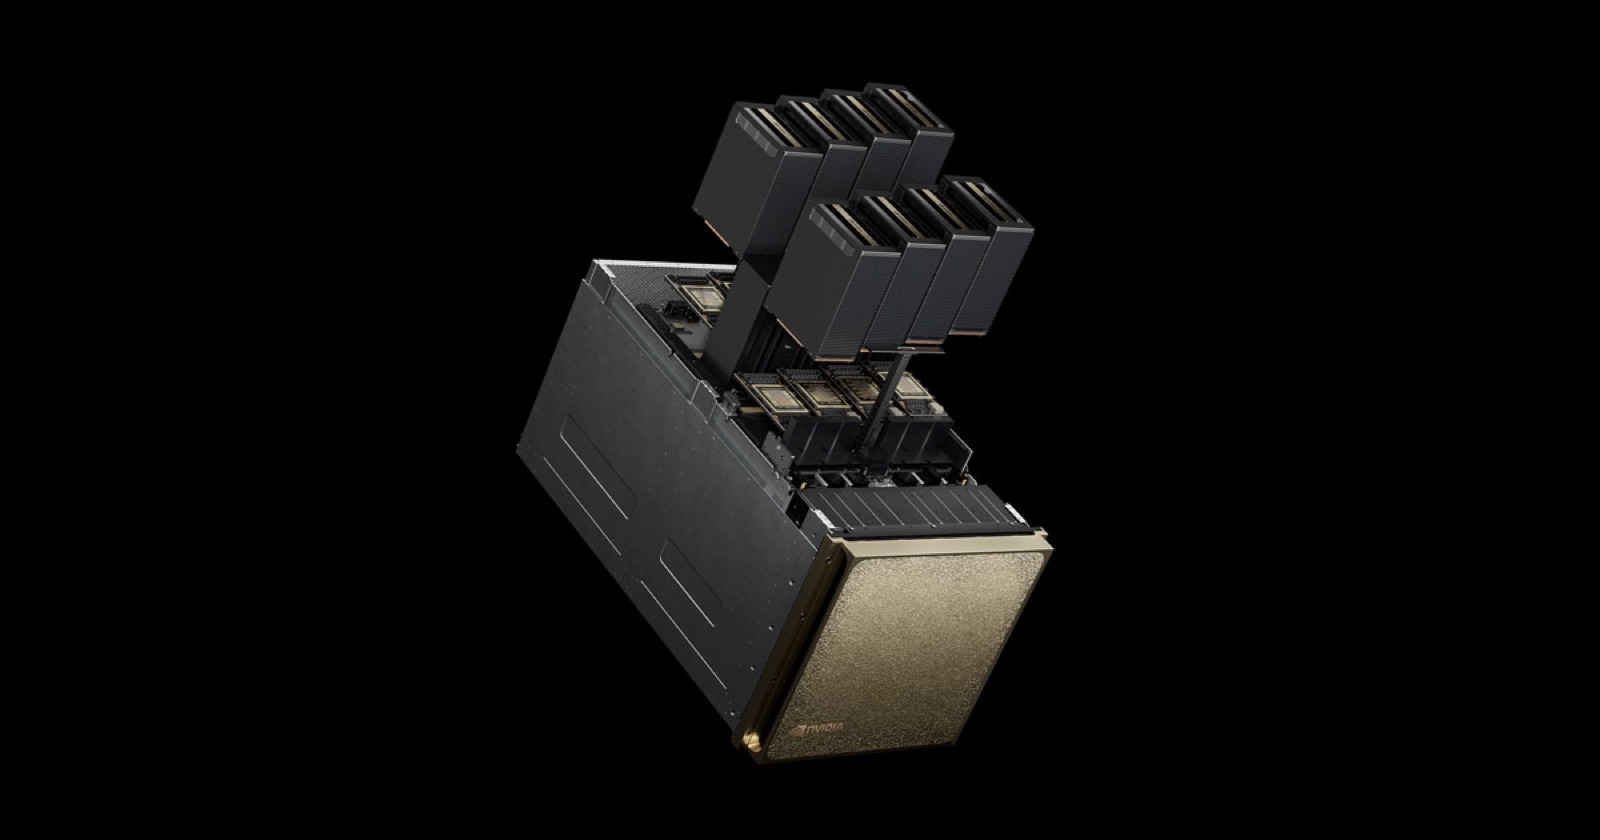
Connect with Blackwell-generation GPU server resource options.
Discuss B200 resources ↗
Explore GPU servers and dedicated cluster configurations.
Discuss B300 resources ↗
Explore rack-scale infrastructure and larger cluster resources.
Discuss GB300 NVL72 resources ↗Plan next-generation rack-scale AI infrastructure requirements.
Discuss Vera Rubin resources ↗GPU model portfolio. Regional availability and configurations are matched to each enquiry.
Plan the model capacity your applications need. Talk to us about Token supply, usage requirements and enterprise service options.
Let's discuss your use case ↗Service scope and supported models are confirmed during consultation.
Bring the infrastructure requirements into the discussion early.
Discuss GPU interconnect, front-end networking, storage networking and oversubscription against your distributed workload.
Review rack density, cooling design, facility power arrangements and acceptance conditions with the operator.
Define dataset capacity, local scratch space, checkpoint throughput and data transfer requirements.
One conversation to start. A structured process to move your project forward.
Tell us your workload, GPU requirements and preferred regions.
Compare configurations, capacity options and commercial terms.
Align delivery milestones and service responsibilities with your providers.
From technical configuration to service responsibilities, we help bring the right questions into the conversation before a commitment is made.
Explore our service framework ↗NEXFLOW MATRIX PTE. LTD. is a Singapore company focused on connecting enterprise AI requirements with GPU resources and Token services.
Practical guides from NEXFLOW MATRIX for scoping enterprise AI requirements.
From GPU count to acceptance: the questions to put in your resource brief.
Read the guide ↗Estimate input, output and peak demand before discussing a service quote.
Read the guide ↗Align configuration, milestones and responsibilities before a project starts.
Read the guide ↗Practical answers for planning your deployment.
NEXFLOW acts as a resource sourcing and coordination partner. Resource operators, contracting roles and service responsibilities are identified for each project.
Model selection, service access, pricing units and capacity are confirmed against your requirements. Supported capabilities are confirmed for the selected service.
Yes. We welcome enquiries from global businesses and assess resource location, delivery feasibility and project conditions individually.
Hardware images: NVIDIA official product visuals. Platform reference images; supplied systems may differ. B300 visual shows DGX B300, while the Toronto proposal specifies Dell servers.